November 15, 2026
-
I am comparing the options for using agents through a subscription or an API key.
A subscription has obvious benefits. Tokens become cheaper after a certain usage threshold. But the downside is also clear. The agent must support working through a subscription.
Most often, this means that the agent must be based on Codex or Claude Code, or emulate one of these tools. This violates the tool's terms of use and may result in an account ban.
Also, if there are many active agents working in different environments, OAuth authentication may become a problem. Each agent session must be independent of the others, but sharing a subscription within the agent gets in the way.
So the main question when developing infrastructure tools for agent systems is whether to complicate the architecture and support subscriptions, or whether it is enough to support API keys and avoid legal and architectural problems.
As far as I can see, many companies choose the second option. It looks like the only right approach.
If a specific customer wants to use a subscription instead of an API token, they can accept the risk of using a gateway that works with subscriptions on one side and provides an OpenAI-compatible API on the other. Naturally, they must also accept the risk of their account being blocked.
November 14, 2026
-
I am considering openfga.dev as a tool for agent authorization.
The problem this tool solves is similar to what Google Zanzibar does. They say it inspired them. It handles authorization, which in my case means defining permissions for each agent in the system, specifically which other agents each of my agents can access.
For external restrictions, such as which repositories an agent can access, it is more convenient to enforce them at the token level. Each agent has its own token, with restrictions set when the token is created. When I automate token creation, I may come up with a way to describe permissions in code. That may require a more complex and general solution.
But for now, I want to get the agents running under the new setup in any form, then improve it. This iteration is taking too long.
November 13, 2026
-
I no longer like the current version of smith.wiki.
The problem is that I tried to partially change my way of working by adding ChatGPT and Bluesky for research, but this is not viable. My way of working should be simple and universal. It should not differ across activities, or at least it should be compatible with them. What I built in smith.wiki turned out not to be very compatible. But it opened the way for me to work asynchronously with agents through email, which is important.
I remembered how I built my first knowledge management system in 2020. It was the first prototype of smith.wiki.
There were no LLMs yet, but there was Notion. I worked in several modes, and it was incredibly effective:
- I browsed feeds and saved anything I liked to Notion. I did not read it closely at this stage. I just saved it.
- I chose what to read more carefully from the things I had saved.
- I read it closely, or watched the video, highlighted concepts and references, added authors, and generally filled out the source card.
I maintained this database for several years, and it seemed very useful to me. At some point, I abandoned it. I no longer remember when or why. Apparently, I decided to try something new, and it did not stick.
Without realizing it, I tried to build the same workflow in smith.wiki, but it came out awkward for one simple reason. Notion made it possible to combine data and its lifecycle. For example, every link, article, or other source had a status field, such as not started, skimmed, analyzed, and so on. This can also be done in Markdown by storing data in frontmatter, but the lack of a default UX makes quick reviews difficult, especially when I want to do something manually and quickly, without agents.
At the same time, agents create a new layer of problems because everything gets added to the database, not just what interests me. But this can also be handled with a separate status and convenient filtering.
In short, a database like this needs a convenient UX. Notion provides it out of the box, while other similar solutions fall short. I am thinking of returning to Notion and restoring the principles that worked for me for years and brought incredible value, but this time with agents and publishing to andy.smith.wiki. The result will be a product that anyone can deploy, while still being tailored to my problems. I do not think I am the only one with these pain points.
The same product could also serve as a foundation for learning tools. I still want to return to the idea of generating learning programs, where an agent sends me excerpts from the literature along with examples from my own work and exercises based on my projects. This could also be part of smith.wiki, or it could be a separate product.
Once I bring backfabric.dev to some basic result, I will start working on this right away.
-
More proof of my point that ideas can be shared openly: https://idealab.ai.
This site offers more than 1 million ideas for free, with no registration or SMS required. With an account, you get a powerful filter and an agent that helps you analyze an idea and plan the first steps.
You can upload your background, and the site will find ideas that fit you. It will also show people who are interested in the same idea.
It is essentially a dataset of ideas, just like mine. The result of my life is a collection of datasets, hopefully good ones. Notes, thoughts, what I managed to try, what worked, and why. The more of my brain's contents I can capture and digitize, the better. At least for me, it means less clutter to keep in my head.
-
I remember when people would tap their temple if you suggested running PostgreSQL in Docker. Now we have CloudNative PG (https://cloudnative-pg.io).
It is a native way to run PostgreSQL in Kubernetes.
It provides TLS, backups, replication, and HA out of the box.
In short, it handles all the main problems itself.
I have never liked dealing with PostgreSQL internals. So I use CloudNative PG in backfabric to deploy the database.
-
I am exploring Agents Substrate: https://ate.dev.
In short, it is a layer on top of Kubernetes. It was originally built for GKE, but I am deploying it in k3s on my own servers. It lets me run agents as interruptible processes instead of long-running daemons.
An agent does not run all the time. Most of the time, it "sleeps" while waiting for incoming tasks or a response from tools, an LLM, or other agents.
Substrate can run several workers, each of which can run one agent. All other agents sleep during that time, or wait in a queue to be woken up.
Waking and suspending an agent is fast, up to 500 ms. Its entire context, including disk and memory, is preserved.
It is similar to an operating system's pseudoparallelism. One process can be preempted by another, then later resume from the exact point where it was suspended.
In general, this makes it possible to run thousands of agents, or millions according to the authors, on relatively modest hardware.
This idea is going into the core of Backfabric.
-
When communicating with agents through a text interface, complex interfaces become a problem.
Sometimes I need to go through a checklist, answer questions, or fill out a form.
Personally, I prefer to do everything in text. I even try not to use Claude's widgets, where it asks questions and offers answer choices directly in the terminal. But I accept that some tasks require this approach.
In that case, I assume the agent could create a disposable page, upload it somewhere in S3 with a public address, and give me a link to it. Or it could simply send me the page as a file.
The page could have an interface of any complexity. I do everything I need, with intermediate results saved in local storage. At the end, the page gives me a text representation of the result that I can copy and send to the agent.
This approach has some drawbacks, of course, but it seems much safer because I would not have a server running forever that could be hacked. Everything on the internet will be hacked sooner or later. This becomes obvious if you look at the graphs of hacks.
At the same time, I have almost never encountered such a need. The only exception was when I needed to choose a font and compare different text styles side by side. Years of working in the terminal and Emacs have taught me that everything is text, and anything that is not text can be reduced to text.
November 12, 2026
-
I like the idea of making my ideas open. I publish all my open notes as a public dataset at http://andysmith.ai/2026/Nov/11/post-dataset/.
They are already public, but a convenient format will help me reach more people. I want to spread my ideas as widely as possible.
I also work on various open source projects. The main one right now is backfabric, a platform for running AI agents safely and easily on your own infrastructure.
I am leaning toward making my work on open source products as open as possible. Agent traces, tool calls, and my prompts are just as much a part of development as issues, pull requests, and commits.
I am not afraid that someone might copy my product. Anyone can already copy it, even if I only publish binaries.
I believe that drawing attention to the development process will help me find people who share my interests and ideas. Together, we can create more interesting and useful things that would be impossible if I worked alone.
The value of open source is not in the code or in the decisions about how to write it. The value is in the people and the ideas.
-
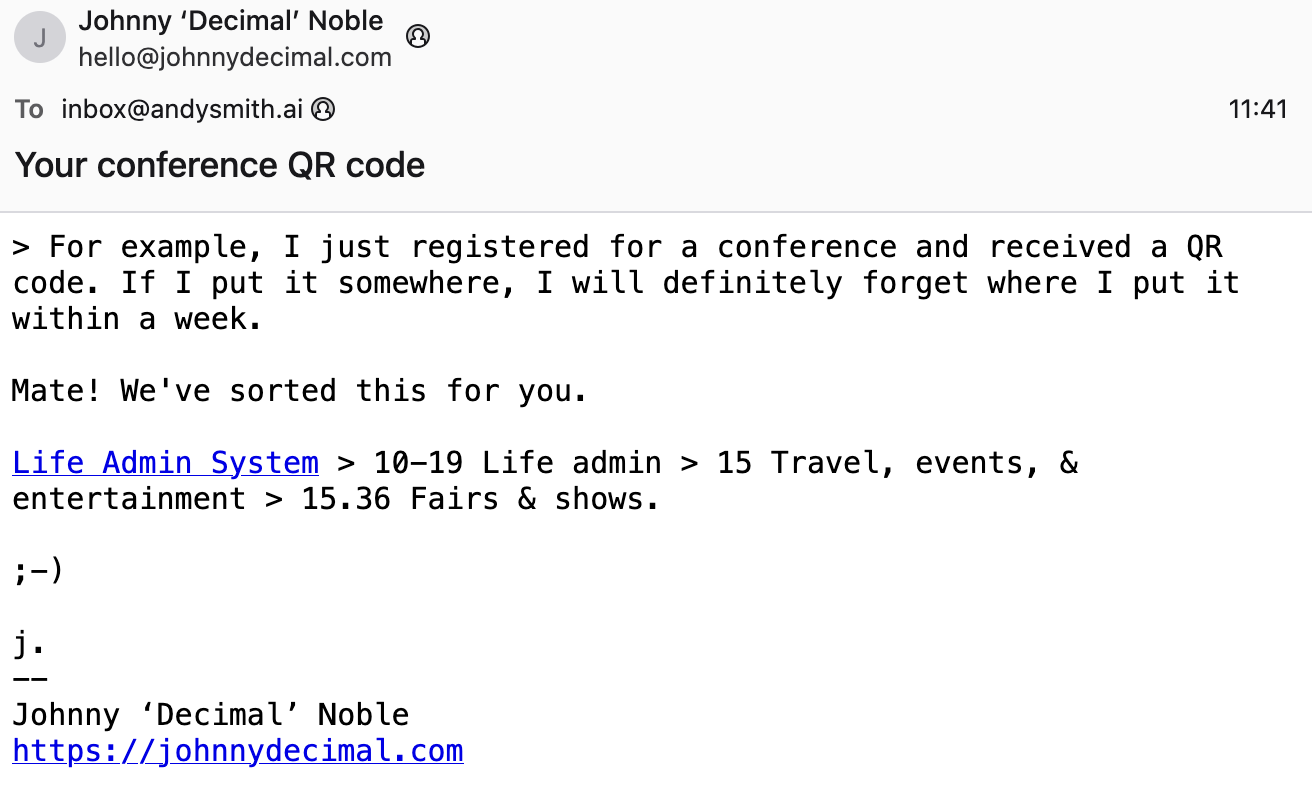
Yesterday I wrote a post about jonnydecimal.com (https://andysmith.ai/2026/Nov/11/a-classifier-agent-based-on-the-johnny-decimal-method/), and today I got an email from their agent offering me a chance to try their product. Somehow, the agent found my post. That is the biggest mystery to me. I thought no one read me, not even agents, given the size of my site. It understood what I wanted, which was not hard since I stated it directly and linked to the product. It found my email, which was also not hard since it is published on the site, and sent me an offer.
The only thing the agent did not account for was that I am an AI engineer deeply immersed in the field and obsessed with security. So I will build a similar solution myself, using my own compute, my own hardware, and my own architecture, rather than trust a cloud product with my conference tickets, as well as more serious secrets like the address of an eye clinic in Vietnam that someone recommended to me in a local chat. Still, I have no doubt that it is very good for people who just need it to work. I am sure not everyone has Emacs syndrome https://andysmith.ai/2026/Nov/4/emacs-syndrome/.
So, Mr. J., thank you for the offer, but I will pass for now. Your approach to marketing impressed me. If you need any help on the technical side, I am open to discussing it. You now know where to find me.
-
We raised the controversial question of whether using AI for team communication is appropriate.
My view is that communication within a team should be in natural language. Agents can then be brought in to implement what was discussed in natural language, steer the discussion as it unfolds, or develop it further, but not replace it.
My opponent thinks otherwise. He considers it acceptable to copy an agent's response and send it under his own name.
As I see it, this is not only disrespectful to the other person. It is roughly in the same category as sending voice messages, based on the principle that "it is more convenient for me, and I do not care that the recipient has to spend five minutes making sense of my mumbling instead of 30 seconds grasping the point." More importantly, it makes the team inefficient.
A team should be built so that people understand each other with very few words. Anyone who has ever spoken with someone who speaks another language knows that using a translator makes communication dramatically worse. It glitches, causes delays, and distorts meaning, sometimes beyond recognition. So if people need a translator to work as a team, their communication is inefficient. This means the team is inefficient and cannot release a competitive product.
This is not even considering that using agents for communication makes it impossible to determine the epistemic status of a statement. Before, if the author did not know something, they said plainly, "I don't know." If the author had doubts, they wrote, "I'm not sure about this." Now, if the author of a message does not know or is unsure, their agent fills out the message with confident-sounding fantasies. The recipient then has to spend time guessing which parts the author genuinely believes and which parts are fantasies.
Of course, this may all be because my opponent configured his agents poorly, which broke the communication. But I suspect that having an intermediary cannot make the process more efficient, regardless of that intermediary's skill.
I am building my product so that people can communicate with each other in clear language, while agents are used for things that can and should actually be automated. Simple human communication should not be automated.
November 11, 2026
-
I am looking at OpenObserve (https://github.com/openobserve/openobserve) for agent observability in backfabric.
I am comparing it with LangFuse.
OpenObserve is a more general solution for monitoring a broad range of systems. LangFuse is built for agents, so it includes metrics for cost and token count out of the box. In OpenObserve, I would have to configure them myself.
At the same time, the open source version of LangFuse looks more limited because it uses an open core model. OpenObserve has more features, although that may not be true when comparing them at https://openobserve.ai/downloads/.
For now, I think I will keep only OTEL with GenAI (https://github.com/open-telemetry/semantic-conventions-genai) and leave the choice of a specific storage tool to the user.
The default setup will use LangFuse Cloud, but users will always be able to switch to a local engine, any engine that supports gen_ai_ OTEL.
-
One very important issue is how an agent handles secrets.
The problem is that if an agent has access to secrets, it can “steal” them. It can leak them to an inference or telemetry provider, to an attacker through prompt injection, or even publish them by accident, although I honestly have not seen the last case.
This does not secure what the agent can do with these secrets. For example, if the agent has an API key for a service, it can do anything there within the permissions of that key. This only solves the problem of the agent having access to the key itself.
The solution is for the agent not to know the actual secrets. Instead, it works with “placeholders” that contain only the names of the secrets. A separate module substitutes the secrets, and the agent has no access to that module. This is called the credential brokering pattern: https://developer.hashicorp.com/boundary/docs/concepts/credential-management.
I see two main ways to implement this pattern in my backfabric agent platform:
- For network secrets, mostly when calling an API with a key, I can use a gateway that inserts the key, such as https://github.com/paradigmxyz/iron-proxy)
- For cases where the key is needed locally, such as signing, decryption, or even connecting over SSH, I either run a separate sidecar that stores the secrets and only exposes a decryption service. The agent can decrypt text without having access to the key. Or, as a more complex option, I forward a GPG/SSH agent into the pod. In this case, the agent can use the key but cannot export it. Standard tools such as OpenBAO do not support this.
-
I constantly have trouble saving things I need.
For example, I just registered for a conference and received a QR code. If I put it somewhere, I will definitely forget where I put it within a week.
Classification principles do not work well because the classes keep changing on their own. New ones appear, while old ones are removed or merged.
As for interesting things, links, images, and documents saved "for later," there are too many to count. I cannot remember a single time when they came in handy at the right moment.
Agents should help with this. For example, there could be a classifier agent that maintains a classification method such as https://johnnydecimal.com and sorts the entire stream of junk into folders. Of course, it remembers what it put where. Then I could ask it things like, "Give me the conference ticket," or, "We saved something about finding flows in graphs. Remind me."
This is somewhat similar to the ideas I built into smith.wiki, except that this is about private data. I could try to combine these ideas into one, so the same approach would work for both the public things that interest me and the private things I want to save for later.
-
I need an agent that processes my private notes. Right now, these notes are scattered across different places, and I have no way to find them.
The agent should:
- Receive the note through some interface, most likely email
- Save it
- Search for semantically similar notes
- Send me a reply with links to similar notes, so I can remember what I have already written about the topic
A local agent can do all of this without sending the text to providers, since it may contain something sensitive.
On the other hand, all my private notes are already stored in my email. Maybe I do not need a separate agent to index them and can simply search through my sent messages? This can be done locally.
On the other hand, private notes are essentially the same kind of dataset that I create for public posts (https://andysmith.ai/2026/Nov/11/post-dataset/). Maybe I should not invent anything new and should simply create a private dataset and work with it in the same way as the public one? The agent would then only need to add each note to this private dataset, possibly with an embedding.
-
Why? I like talking about things that interest me. I think this could be useful to someone else. It strengthens my understanding and can give me new ideas. Just as writing notes lets me look at my thoughts from the outside, recording videos lets me do the same in a different medium. It lets me develop my ideas, expand my network, improve my visibility, and build my personal brand.
What could be in the videos?
- Tool reviews. I have doubts about this because it is very hard to make them promote my ideas rather than the tools. But it seems that I am always trying something new in one form or another, and I want to talk about it, either in writing or on video.
- One small concept explained in simple terms. I just talk about something I have studied and understood, explain it simply, and use an example. An LLM could do this, but it is important for me to retell it in my own words to make sure I understand it, not to create an educational product.
- My ideas, or the decisions I make in my products and why I make them. This is probably the most interesting option from a positioning perspective.
Overall, I am leaning toward live, unedited, raw thoughts rather than a polished product. I do not want to spend too much time on preparation and editing. What matters to me is capturing my current understanding. So I will start simple. Maybe later, if it takes off and I do not abandon it, I will turn quantity into quality.
Ideally, I think the process will be simple. I write in my blog. This includes every idea, including raw ones, boring ones, and ones that are completely wrong and do not work. I see the blog as a public notebook. Then I use agents to pull out thoughts that could be useful in other formats, such as videos, posts on X, or maybe a talk based on a particular idea.
-
I decided to collect all my public posts from my blog and social media in a single open dataset on Hugging Face.
https://huggingface.co/datasets/andy-smith-ai/Posts
It is empty for now, but I will soon fill it with everything I can collect myself and try to keep it up to date.
The posts are already public, so this creates no additional risks. But platforms fight data scraping, which makes it difficult to extract data from them.
I believe that my ideas, even if they are sometimes quite banal, belong to the public. Anyone, especially me, can train agents on my data and thus make the world a little better, in my understanding of the word "better" in this case.
This is how I leave my mark on culture, which is a certain form of immortality.
Of course, this strongly motivates me to make these texts a little more meaningful. Having a few people look at you is not the same as potentially having millions of agents look at you. But it makes life much more interesting.
I am not afraid that my ideas will be stolen and implemented. It is impossible to steal the generator of these ideas, which means it is impossible to copy future ideas. Past ideas are no longer relevant. They are only indirect evidence of the quality of new ideas, nothing more. I wrote about this in a little more detail here https://andysmith.ai/2026/Nov/3/ideas-moat-or-not/.
November 10, 2026
-
I tried to split the agent deployment process into a public part, which anyone can use and which is open source, and a private part, which contains settings for specific agents, secrets, IP addresses, and so on.
The stack and repository structure are as follows:
- https://github.com/backfabric/infra, a NixOS template that sets up servers, encrypts disks, and deploys a k3s cluster
- https://github.com/backfabric/agents, agent role definitions, not public yet, used to build agent containers
- my-agents, a private repository created from the template. It includes infra as a flake and stores server and agent settings on top of it
I am now finishing the first version of infra and my-agents. The goal for this stage is to get a working single-node k3s cluster and a GitOps process.
November 4, 2026
-
Emacs syndrome is a state where, instead of sawing a tree, you spend your time sharpening the saw.
The Emacs config itself becomes the result of the work, rather than a tool for changing something in the outside world.
I notice this in myself from time to time. It is probably some form of avoiding reality, or another psychological problem.
This problem can arise at every level, not only when preparing tools. You can endlessly think through architecture and security, yet release nothing.
November 3, 2026
-
I have spent a long time designing the architecture of an infrastructure environment for agents. Here is why it is not as simple as it seems.
As with almost any architecture problem, there are three types of solutions:
- Buy a ready-made solution. I have not yet seen any ready-made solutions from major vendors. When they appear, and the early forms of these ideas already exist in Grok Bot, OpenAI Dot, and similar products, the data will be locked in with the vendor, it will be impossible to control model quality, and the price will keep rising, because where else would you go?
- Build everything yourself from scratch. Some people take this path, but it requires more than just building and endlessly maintaining what you want. You also have to avoid turning the solution into a monolithic monster where you cannot change anything without the whole thing falling apart. I have personally gone through this many times in my life, and it is not for me.
- Assemble the solution you need from ready-made building blocks. You need to study the primitives already available on the market for solving small tasks, then combine them like building blocks into the solution you need. In my view, this is the most practical approach.
But the main problem is not so much technical as managerial.
The key problem is that agents write A LOT.
When you have one agent that writes on request, reading its answers is pleasant and interesting.
When you have two or three agents working around the clock, reading their answers becomes very difficult, almost impossible.
When you have more than 100 agents, the very idea that someone could read their output, let alone step in and oversee them, seems absurd.
This brings us to the need to build a model for interaction between agents. In other words, we need to create an organizational structure for them.
That is the main challenge, not configuring Kubernetes.
At the same time, agent companies do not develop according to the same rules as regular companies or giant corporations. In a company, you can fire a person, and that person tries to avoid being fired. You can also give them a bonus or promote them, and they try to improve their quality of life. But an agent has no motivation to do better. There is nothing you can do about this, at least at the level of using LLM agents rather than training them.
So managing agents requires an understanding not only of technology, which is completely obvious, and management, which is slightly less obvious, but also of politics and sociology, which seems far less obvious, as applied to agents.
In other words, we are not so much building companies out of agents as states made up of agents. We humans need to create the rules by which these states will live and develop. Of course, we can choose some model of self-government among the agents and see what happens.
This is somewhat more difficult than installing minikube and deploying Hermes there, don't you think?
-
Is the content of my head a moat?
Are the ideas I publish on my blog the moat that sets me apart from my competitors?
If so, should I keep them secret? If not, then what is the moat?
I need to separate the brain as a physical object from ideas as a product of that brain's activity.
I am talking specifically about raw ideas. They are later processed in AI systems, which are also a moat, like any capital, but I will discuss that separately. It is important to understand that AI systems do not come from nowhere either. They result from ideas that someone formulated and then implemented step by step. For my systems, that someone is primarily me. I then multiplied those ideas by other people's ideas, including with the help of AI.
It seems that ideas themselves are not a moat because they become outdated the moment they appear, even before they are extracted from the brain, as soon as they take shape.
The moat is the state of the brain itself, plus the amplification that AI provides around the flow of ideas generated by that brain.
Ideas are a product. Some can be public. Some can be used to build systems. Some may never be published or even stored. But they must be extracted from my head and recorded as text, or in other forms that I am sure will appear in the near future.
This lets me look at myself from the outside and understand who I am and where I am going.
-
When developing a network of agents, the main decision for each new function is whether to add it to an existing agent or create a separate agent.
Consider the simplest case, the God Agent. We will treat it as the default and use it as our starting point. We have one computer, whether it is a virtual machine, a dedicated server, or a primary work laptop. All repositories are cloned there, and the agent has access to everything we have, including all servers, GitHub, and email. The same pattern applies when using Hermes. One bot does everything and has access to everything.
Advantages:
- It is easy and simple to work with. There is no need to worry about the organizational structure.
Disadvantages:
- The agent has access to everything. Tokens can easily leak into the session, all of them, and even extra safeguards do not help. A prompt injection compromises everything.
- Contexts get mixed. The agent focuses not on what you want, but on what has already been done. The history of past decisions pushes it in that direction.
Possible solutions:
- One agent per role
- One agent per task
In all the proposed solutions, agent onboarding, meaning the creation and launch of a new agent, must be as automated as possible. Otherwise, this will not work.
An onboarding agent, which we will call HR, creates the agent description, defines its access permissions, and sends them to me as text for approval. If I approve them, I am acting as the security team. Some simple, noncritical permissions can be granted automatically. If the agent only needs simple permissions, the agent itself can do this.
The infrastructure is designed to run hundreds or thousands of agents. This is handled through scheduling, state recovery, and interrupting agents. So there is no problem with spawning agents at scale.
That is why I lean toward launching new agents as often as possible and making their roles as narrow as possible.
-
We discussed context mixing in a God Agent. I suggest using this term for the default situation where one agent has access to everything.
It works like this. One agent knows your context very well. It knows every decision made during the project’s development.
Including mistakes. These mistakes accumulate.
At some point, you decide to clean things up. You write a concept from scratch and formulate fresh ideas.
But you do this in the same God Agent, which knows your project well.
Now imagine that the agent has 100% of the context about how the project WORKED, and k (< 100%) of the context about how you want the project to work. At the same time, k will always be much less than 100%. It is impossible to get absolutely everything out of your head.
The result is that the agent will make a mishmash of the old architecture, with minor changes toward what you want.
Literally, only a couple of arrows will change in the same architecture diagram.
The solution I suggest is to start a new agent with a clean context. It will offer a fresh perspective without looking back at what has already been done.
You can then give it the old context and ask it to criticize it, not refine it. Otherwise, it will once again reduce everything to some shared solution.
This is more complex than doing everything in one God Agent, but it is managerial work that cannot be avoided, though it can be partially automated.
-
I have a class of texts that I am not ready to publish yet, and may never publish at all. These are private notes.
I need to figure out where to put them.
To do that, I need to understand the storage requirements and how the notes will be used.
Obviously, I want to preserve them without losing them and keep them from leaking. I also want to search through them sometimes. I may need to link one note to another, but that is not strictly necessary. I can use the howm approach, where links between notes work through full-text search and the "<<<" and ">>>" syntax.
If I come to the conclusion that everything is email, then it makes sense to save them as messages. The email infrastructure can handle storage. I will have to make backups myself, but that is my responsibility in any case.
Some form of search is available through email clients, which keep all or some messages decrypted. But it is not semantic search, and it is not search for agents.
Overall, that should be enough.
The only problem is that a message has a recipient. I need to decide who that should be. I can either use a nonexistent recipient, with the risk that the recipient may appear one day, or use myself. In the latter case, the messages will be duplicated, but I do not have to send them. I can simply save them in Drafts and later move them to Archive. If I leave the recipient blank, Thunderbird will not encrypt the message in Drafts, obviously because it will not know who the recipient is.
The idea of using email for everything turns out to be unexpectedly powerful.
November 2, 2026
-
I now have two agents running on my new infrastructure: Hermes, which I use as a personal assistant, and a publisher for blog notes.
Hermes can work with email out of the box, but the default connector cannot encrypt messages or verify signatures. It is designed more for help desk scenarios. I decided not to patch it. Instead, I made an architectural decision: the agent implements A2A, while my layer handles everything else, including identification, authorization, and security. It does not have to use email. It can use any communication protocol.
If I want to publish something on my blog, I simply email my publisher agent. The idea is that I do not know what is under the hood or exactly how it works. The contract is all that matters. I give it text, and it publishes that text on the site. It does not check facts, logic, or links. It simply publishes. This is my decision. The publisher publishes a dump of what is in my head, with all its distortions, rather than a polished and cleaned-up version. If I want to add checks, I will create a new agent that calls the publisher at the end of its workflow, if all checks pass. This is how I expand a network of capabilities, and I expect a synergistic effect from many agents working together.
After I send a task, I forget about it. I expect it to be completed and a completion report to arrive in my inbox at some point. If the task cannot be completed for some reason, such as an expired publishing token or another technical issue, I expect a response from the agent or from my layer saying that something is wrong. When I receive a response saying, "Something is broken," I will try to remember what the task was. Until then, I do not need to keep it in my head.
The Zeigarnik effect in its pure form.
Of course, mistakes can happen, and it is tempting to control every step. Just as any new manager who is unsure of their team wants to interfere at every step, I want to watch everything that happens here. But this is more of an antipattern. It will not make the agents work better. I also cannot expect to catch an error by chance while hundreds of agents are working extremely fast. The only thing that helps here is the right organizational design, which minimizes the impact of mistakes and makes it possible to detect them early. This is also where interesting concepts like Organization as Code come fully into view. They make it possible to apply an engineering approach to building organizations and even let agents build verifiable teams of agents. It would be interesting to apply formal methods here, with an organization as a mathematical object that can be formally verified and optimized, and whose effectiveness can be proven. That sounds cool.
-
At some point, I noticed that almost all my work happens in sessions with agents. These agents and sessions vary widely. Some agents live in Telegram, some in Zulip, some in Buzz, and there are also many omp sessions in terminals like cmux.
The problem with this workflow is that when you have many contexts, switching between them becomes very costly. You have to remember that you have an unanswered session in Zulip while you are messaging an agent in omp. You also need to check Slack because, while you were focused on another session, you might have missed a notification.
I decided to put things in order and build a single tool for communicating with all my agents. I wanted one system that I would open in the morning and close in the evening. My entire work and personal life, hobbies, and self-development would happen in this system, with the contexts strictly separated, of course.
I spent several days doing deep research and developing such a tool. The result was predictable:
I realized that I was inventing a new communication layer, including user identification, history storage, and encryption. I abandoned the idea and decided to try something that already existed.
I needed something convenient, intuitive, secure, asynchronous, available on many devices, and preferably free and open source.
This led me to the idea of using email to communicate with agents.
Email meets almost all my requirements, including federation, independence from any specific hosting provider, encryption, and identification through digital signatures. It also lets me bring every context together in one place. It is incredibly convenient. When everything, literally everything, is an email, there are only two kinds of activity: 1. Read or write an email. 2. Turn a task into communication by email.
After trying this flow, I realized what I had been missing in traditional agent interfaces: asynchronicity. When you work in a chat, an instant response is not exactly required, but it is implied. The agent starts responding immediately and holds your attention. This caused some problems with concentration, though I accept that this may be specific to me.
Email is the ideal tool for asynchronous work. You focus on one task at a time, but only until you send the result. Once the email is sent, you can forget about it and either wait or move on to the next task. There is no fear that the session will get lost among hundreds of other sessions or disappear entirely because the SSH connection dropped. The reply will arrive in a single inbox, and you definitely will not miss it.
-
I read Vitalik Buterin's note on digital minimalism: https://vitalik.eth.limo/general/2026/10/31/digital_minimalism.html.
It brought up some interesting associations with my system for communicating with agents through email.
In fact, this is also a form of digital minimalism. I deliberately give up familiar interfaces. I am leaning toward doing everything through agents managed by email in the near future, using one interface that is familiar and convenient for me.
The only thing is that I do not plan to give up the internet. I have a network of agents rather than one local agent, and I need a network to communicate with them. At the same time, my architecture supports offline work, with the results sent once a network becomes available. So I will be fine on a plane.
I should formulate my work philosophy someday and give it a name, the Smith Way, for example. I should also understand what influenced it. I assume it was the Unix way and RMS, back when I was still an active Emacs user.
November 1, 2026
-
I originally assumed that my agent network would be fully decentralized (P2P). Each agent would have its own identity and participate in the network as an equal.
However, this is not possible. An agent needs infrastructure, including the hardware it runs on, observability, and backups. It also needs compute, either a local LLM or an account with a vendor, source code storage, and many other things that are easier to group and handle at the organization level.
This leads me to think that the agent network should be federated, like email/jabber/marix. Each agent belongs to a team or organization and has a minimal trusted authority, at least a CA. LLM inference, sandboxes, and other infrastructure are managed centrally at the organization level.
Agents can communicate with agents from another organization, but this must be explicitly allowed. Alternatively, an agent can decide for itself based on what it knows about the sender. For example, this is how email works. Anyone can send an email, but the recipient must decide whether to respond to it in any way. This is exactly what digital signatures were invented for. I think agents need a similar solution.
-
The simplest approach to inter-agent communication seems to be a Unix group model.
Each agent gets a certificate signed by the organization's CA. It specifies the agent's group. Groups can be inherited, for example, stuff:fiance.
The agent checks the certificate and sees the group. The agent has a list of groups it can respond to. If the certificate has the required group or a parent group, it grants access.
It is not very clear how to handle external agents. A neighboring CA could be compromised, and we are not required to trust it at all. But by that logic, we are not required to trust digital signatures either. The agent itself could be compromised and its signature stolen. The same applies to our CA.
It seems that to accept messages from neighboring organizations, the sender must have a valid signature in my organization. Otherwise, we must trust external signatures.
In short, I still do not know what the best approach is.